Breaking Down Data Silos: The Enterprise Case for a Lakehouse
The companion to this piece described a condition every large organisation recognises: six systems, each holding a piece of the truth, none agreeing with the others, and an expensive manual apparatus built to paper over the gap. This post is about an architecture that addresses it without the two moves that usually fail , ripping everything out and consolidating, or building another stale warehouse. It’s called a data lakehouse, and the case for it is less about technology than about finally being able to see the organisation whole.
The core idea, in plain terms
A data lakehouse is a layer where all your data can sit together, at full detail, in an open format, queryable as one without first being pulled out of the systems that run your business and crammed into a single new one.
That’s the whole idea, and the “without” is the important part. You don’t consolidate the source systems. They keep running, doing their jobs. What changes is that the data from all of them lands in one place designed to hold it together and let you ask questions across it. The systems stay separate; the data stops being trapped.
Mechanically the data sits in cheap, open storage rather than inside a proprietary database. An open table format on top gives it the reliability a warehouse used to provide: consistent reads, the ability to evolve as sources change, the ability to look at the data as it stood at a past point in time. And a query engine reads it where it lies. Nothing is locked into one vendor’s box, because the data is in an open format that many tools can read.
What changes when the data sits together
The abstract benefit is “one source of truth.” The concrete benefits are more interesting, and they’re what actually justify the work.
You can finally ask whole-organisation questions. The customer in the CRM, the billing system, and the service platform can be resolved to one customer, so “what is this customer’s complete relationship with us” becomes a query instead of a project. The questions that used to take three weeks of data-wrangling become answerable in an afternoon.
The gaps between systems become visible, and the gaps are where money lives. Revenue leakage hides in the seam between what was delivered and what was billed; fraud hides in the seam between two systems that each see half the signal; a compliance risk hides in the fact that no one system holds the full evidence. When the data sits together, the seams become inspectable. You can reconcile what one system says against what another says, continuously, instead of once a quarter in a meeting.
Your analysts get their time back. When the picture is already assembled, your best people spend their hours analysing it instead of building it. That shift from assembling data to using it, is often the single biggest practical return, and it’s the one that’s hardest to put on a slide.
And history becomes an asset rather than an archive. Because the storage is cheap and open, you can afford to keep years of detail queryable, not boxed up and effectively gone. Patterns over time (in customers, in operations, in risk) become visible because the history is actually reachable.
Why not just consolidate, or just build a warehouse
It’s worth being direct about why this beats the two usual instincts, because an enterprise buyer has seen both and been burned.
Consolidation is a multi-year, high-risk migration that fights a tide it can’t win, because new needs keep spawning new systems. The lakehouse doesn’t ask you to remove anything. The source systems stay; the data joins. You get the single view without the open-heart surgery.
The classic warehouse copies everything into one expensive, rigid, often-stale store, and frequently becomes just another system with just another version of the numbers. The lakehouse keeps the cheap-storage flexibility of a data lake but adds back the reliability a warehouse had, so you don’t trade coherence for cost or freshness. And because it queries data in open formats, it sidesteps the lock-in that makes a proprietary warehouse a decision you can’t easily reverse.
The property that matters most over time
There’s one benefit that feels abstract until the day it isn’t: because the data sits in open formats on storage you control, it stays yours. Any engine that reads the open format can read it, including tools the original vendor has nothing to do with. There’s no export process to get your own data back, because it was never locked in.
The test is a question worth putting to any data platform decision: if we stop working with this vendor in three years, what happens to our data? If the answer involves an export, a proprietary format, or a professional-services engagement to retrieve your own information, you are renting access to it. With a lakehouse built on open foundations, the answer is “nothing happens, it’s in open tables in our storage, and we keep querying it.” That’s not a feature anyone demos. It’s the thing you’re grateful for the third time a contract comes up for renewal.
How Synaptique approaches it
This is the architecture Synaptique builds, so it’s worth being concrete rather than abstract about it.
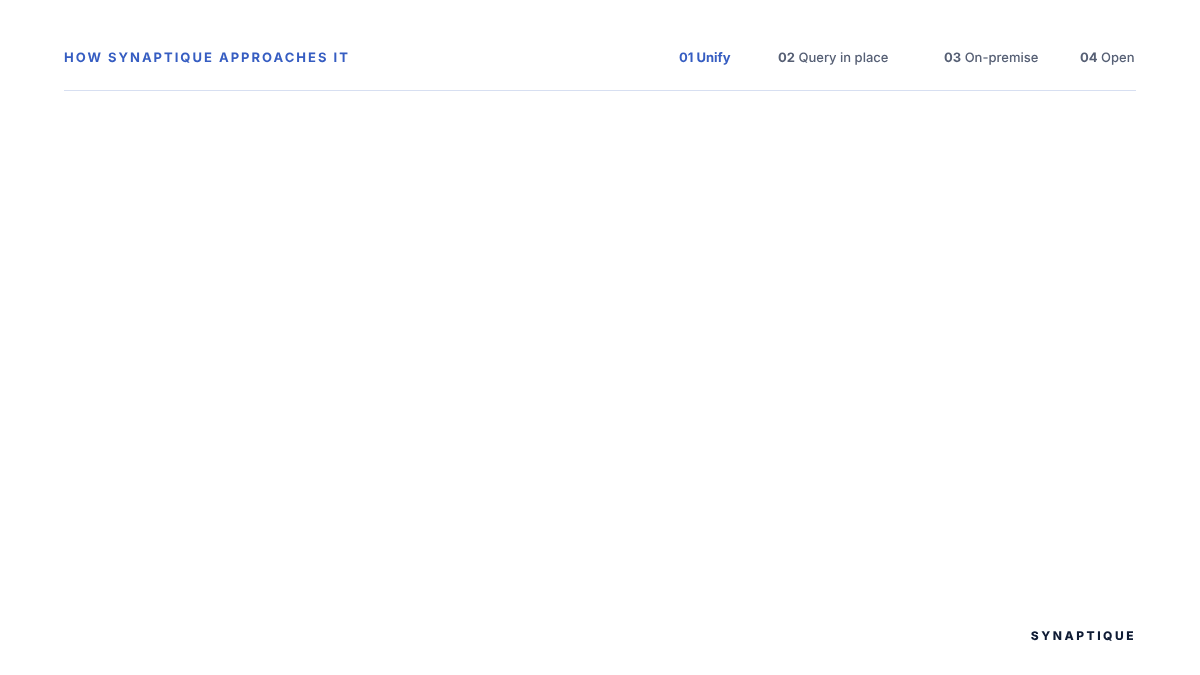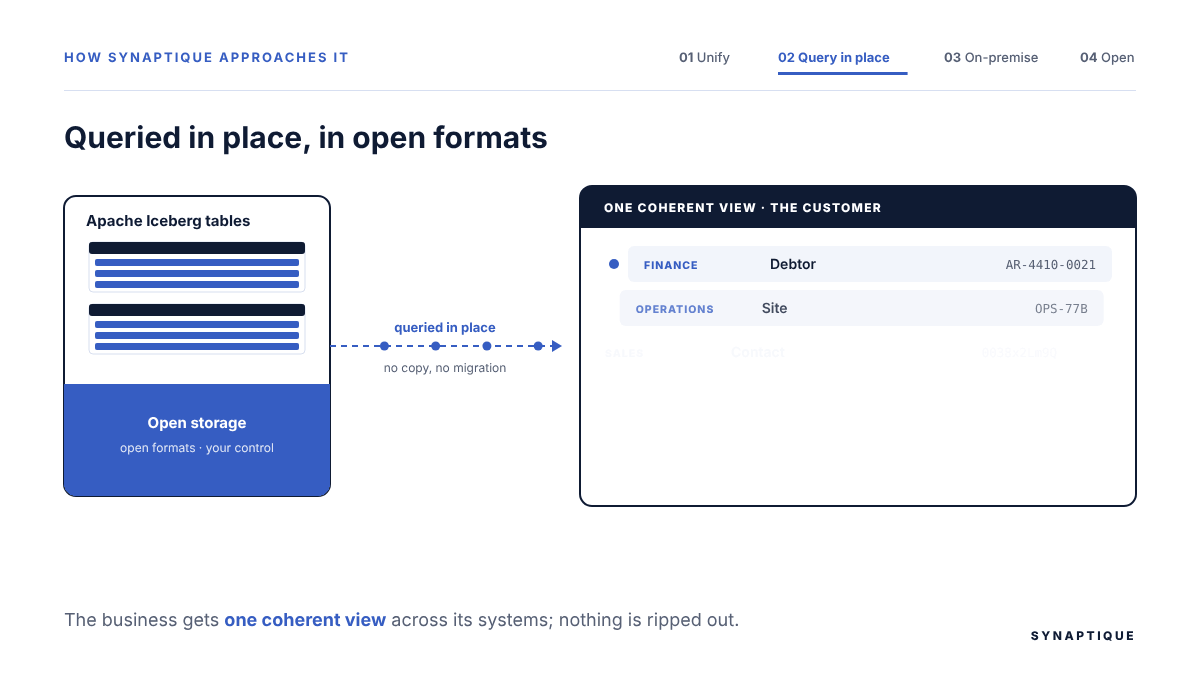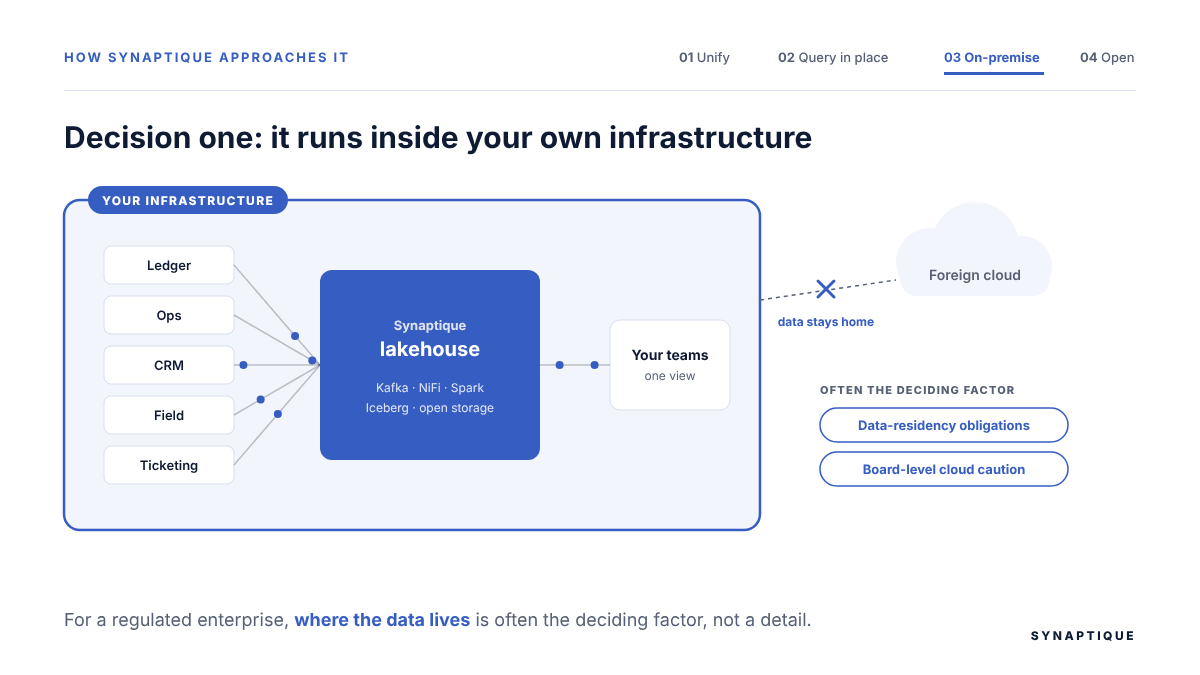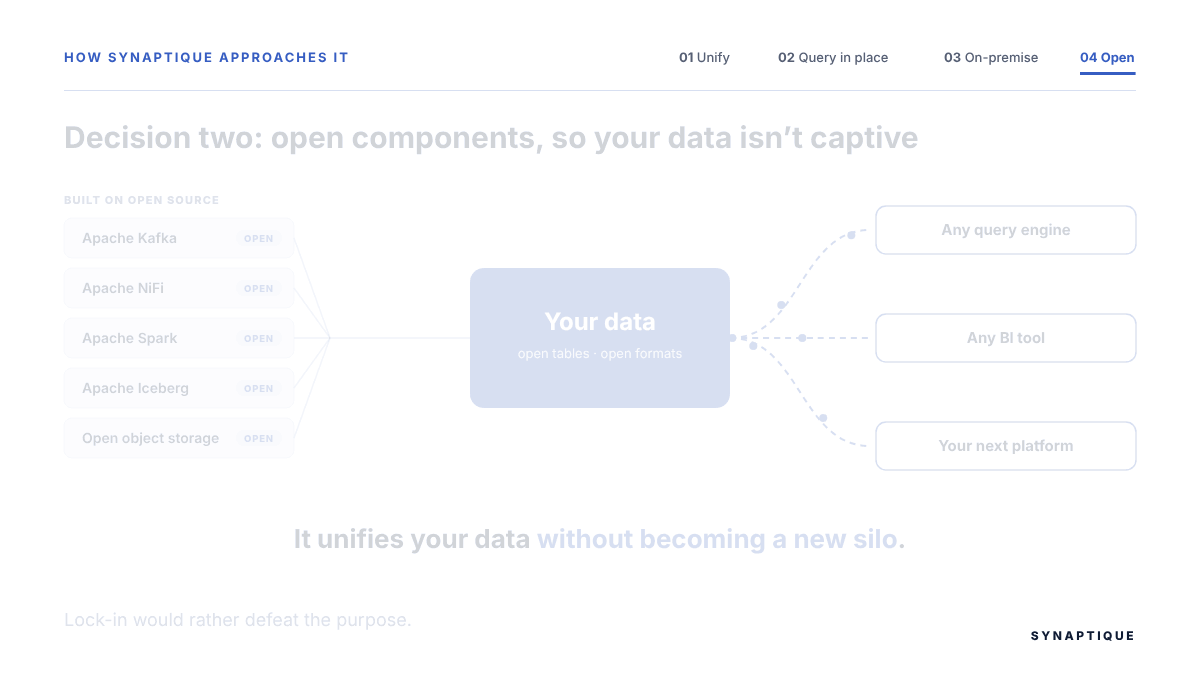
Synaptique provides an open data lakehouse platform that lets an organisation unify data across its systems without a consolidation programme. Data from the source systems is brought together (through Apache Kafka and Apache NiFi for streaming and batch ingestion, Apache Spark for loading history) into Apache Iceberg tables on open storage the organisation controls, or cloud storage where that’s preferred. It’s queried in place, in open formats, so the business gets one coherent view across its systems while the systems themselves keep running.
Two decisions matter especially for a large or regulated enterprise. It can run on-premise, inside your own infrastructure, which for organisations with data-residency obligations or simple board-level caution about foreign cloud is often the deciding factor rather than a detail. And because it’s built on open components, your data isn’t captive, the platform unifies your data without becoming a new silo you’re locked into, which would rather defeat the purpose.
What it doesn’t fix, honestly
A lakehouse doesn’t repair bad data. If a source system holds wrong or incomplete records, unifying them produces a complete, confident view of a wrong picture, which can be worse than knowing you’re missing something. Data quality at the point of ingestion is the first job, not an afterthought.
It doesn’t remove the need to decide what the shared truth is. Resolving the customer in six systems to one customer requires agreeing what counts as the same customer, a business decision, not a technical one, and often a harder conversation than the engineering. The architecture makes the unified view possible; people still have to define it.
And it isn’t a project you finish. Sources change, new systems arrive, and the lakehouse ingests them too , which is exactly the point, since it’s built to absorb the next system rather than be replaced by it. But it’s a capability you run, not a box you install and walk away from.
Where to start
Not with a platform-wide programme. Pick one question you can’t currently answer cleanly because the data is split (a single customer’s complete relationship, the real end-to-end cost of one process, the reconciliation between two systems that never quite agree) and unify just the data that question needs. One question, the systems it touches, a real answer.
That bounded start does two things: it delivers something useful quickly, and it proves the approach on your own data before you commit to more. The whole-organisation view is built one answerable question at a time, not in a big bang.
Synaptique runs exactly that kind of scoped start (one cross-system question, unified on your own data, answered) as the way into the larger platform. If there’s a question your silos won’t let you answer, that’s the conversation to have. Book a call now